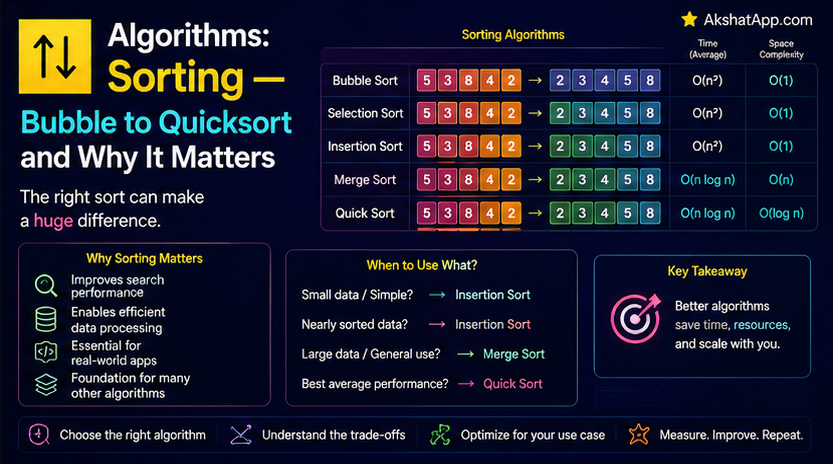
Post #5’s exercises had you build a working sort from a binary search tree — insert everything, traverse in-order, done. That was a genuine, correct sorting algorithm, and it is also not how any real language actually sorts your data. This post covers the sorting algorithms that are, starting with the simplest possible approach and ending with the genuinely sophisticated hybrid running invisibly behind sorted() every time you call it.
Bubble Sort: The Simplest Possible Approach
Repeatedly step through the list, comparing adjacent pairs and swapping them if they’re in the wrong order, until a full pass produces no swaps at all.
def bubble_sort(items: list) -> list:
    items = items.copy()
    n = len(items)
    for i in range(n):
        swapped = False
        for j in range(n - i - 1):
            if items[j] > items[j + 1]:
                items[j], items[j + 1] = items[j + 1], items[j]
                swapped = True
        if not swapped:
            break  # already sorted — no point continuing
    return items

print(bubble_sort([5, 2, 8, 1, 9]))  # [1, 2, 5, 8, 9]
Using Post #7’s Big O notation directly: bubble sort is O(n²) — nested loops comparing every pair, exactly the quadratic pattern Post #7 flagged as a common, often-unintentional performance trap. It is taught not because it is practical (it genuinely is not, for anything beyond small or educational datasets) but because it is the clearest possible introduction to the fundamental idea of comparison-based sorting.
Selection Sort and Insertion Sort: Also O(n²), Also Rarely the Right Choice
def selection_sort(items: list) -> list:
    items = items.copy()
    for i in range(len(items)):
        min_index = i
        for j in range(i + 1, len(items)):
            if items[j] < items[min_index]:
                min_index = j
        items[i], items[min_index] = items[min_index], items[i]
    return items
Selection sort repeatedly finds the minimum remaining value and places it correctly — also O(n²), for the same nested-loop reason as bubble sort.
def insertion_sort(items: list) -> list:
    items = items.copy()
    for i in range(1, len(items)):
        key = items[i]
        j = i - 1
        while j >= 0 and items[j] > key:
            items[j + 1] = items[j]
            j -= 1
        items[j + 1] = key
    return items
Insertion sort builds a sorted portion of the list one element at a time, inserting each new element into its correct position — worth knowing specifically because it is genuinely, practically efficient for small or nearly-sorted data, a real exception to “always avoid O(n²) algorithms” worth remembering.
Merge Sort: Divide and Conquer, Guaranteed O(n log n)
Merge sort splits the list in half repeatedly until each piece has a single element (trivially sorted), then merges those pieces back together in correctly sorted order.
def merge_sort(items: list) -> list:
    if len(items) <= 1:
        return items

    mid = len(items) // 2
    left = merge_sort(items[:mid])   # recursively sort the left half
    right = merge_sort(items[mid:])   # recursively sort the right half

    return _merge(left, right)


def _merge(left: list, right: list) -> list:
    result = []
    i = j = 0
    while i < len(left) and j < len(right):
        if left[i] <= right[j]:
            result.append(left[i])
            i += 1
        else:
            result.append(right[j])
            j += 1
    result.extend(left[i:])
    result.extend(right[j:])
    return result

print(merge_sort([5, 2, 8, 1, 9]))  # [1, 2, 5, 8, 9]
Using Post #7’s notation: splitting in half repeatedly is the log n factor, and merging requires touching every element at each level, the n factor — together, O(n log n), a genuine, guaranteed improvement over the O(n²) algorithms covered above, in every case, not just on average.
Merge sort is stable — equal elements retain their original relative order — a genuinely important property for sorting complex records where you might sort by one field and need ties broken by original order.
Quicksort: Also O(n log n) Average, and Often Faster in Practice
Quicksort picks a pivot element, partitions the list so everything smaller goes to one side and everything larger to the other, then recursively sorts each side.
def quicksort(items: list) -> list:
    if len(items) <= 1:
        return items

    pivot = items[len(items) // 2]
    smaller = [x for x in items if x < pivot]
    equal = [x for x in items if x == pivot]
    larger = [x for x in items if x > pivot]

    return quicksort(smaller) + equal + quicksort(larger)

print(quicksort([5, 2, 8, 1, 9]))  # [1, 2, 5, 8, 9]
Quicksort’s average-case complexity is O(n log n), matching merge sort — but its worst case (Post #7’s distinction directly relevant here) is O(n²), occurring when the chosen pivot repeatedly fails to split the data evenly, most commonly with already-sorted or reverse-sorted input and naive pivot selection.
Why Quicksort Often Wins in Practice Despite Matching Merge Sort’s Big O
This is a direct, satisfying payoff of Post #1 and Post #3’s hardware coverage: quicksort typically sorts in-place, working directly within the original array’s memory with minimal additional allocation, while merge sort’s merging step (as written above) creates new lists at every level of recursion. Just as Post #3 explained that arrays’ contiguous memory layout benefits from CPU cache locality, quicksort’s in-place operation tends to work with data that stays in cache more consistently than merge sort’s constant allocation of new sublists — a genuine, hardware-level reason quicksort frequently outperforms merge sort in real, measured benchmarks, despite both sharing the identical O(n log n) average-case classification Post #7 would assign them.
What Python’s Actual sort() Uses: Timsort
numbers = [5, 2, 8, 1, 9]
numbers.sort()          # in-place
sorted_copy = sorted(numbers)  # returns a new sorted list
Neither of Python’s built-in sorting functions uses bubble sort, plain merge sort, or plain quicksort — Python uses Timsort, a hybrid algorithm specifically designed to combine insertion sort’s genuine efficiency on small or nearly-sorted data (covered directly above) with merge sort’s guaranteed O(n log n) worst-case performance for larger, less-ordered data. This is worth knowing not as trivia, but as direct confirmation of a theme running throughout this entire series: understanding the fundamentals covered in this post is what makes it possible to appreciate exactly why a real, production sorting implementation is engineered the specific way it is, rather than treating sort() as an unexplained black box.
Real-World Use Cases
Choosing insertion sort for small or nearly-sorted data: Directly covered above — this is a genuine, practical exception where an O(n²) algorithm is the right engineering choice, not a mistake.
Choosing merge sort when stability or guaranteed worst-case performance matters: Sorting records where original order must be preserved among equal elements, or any context where an adversarial worst-case input is a genuine risk (Post #7’s worst-case coverage applies directly).
Trusting the language’s built-in sort for virtually everything else: For the overwhelming majority of real-world sorting needs, Python’s Timsort (or the equivalent well-engineered built-in sort in any other language) is the correct choice — understanding this post’s algorithms is about genuine comprehension, not a suggestion to hand-roll your own sort in production code.
Common Mistakes and Gotchas
⚠️ Mistake 1: Implementing your own sort in production code instead of using the language’s built-in
Covered directly above — Timsort and similarly well-engineered built-in sorts have been extensively tested and optimized far beyond what a hand-rolled implementation typically achieves; this post’s algorithms are for understanding, not for replacing sorted().
⚠️ Mistake 2: Assuming quicksort’s worst case can never happen Naive pivot selection (always picking the first or last element, for instance) on already-sorted input triggers quicksort’s O(n²) worst case directly — production implementations use more sophisticated pivot selection specifically to make this scenario extremely unlikely, but understanding it can occur matters for genuinely adversarial-input-sensitive code.
⚠️ Mistake 3: Assuming merge sort is always the safer choice because of its guaranteed worst case Covered directly above — merge sort’s guaranteed O(n log n) worst case comes at the cost of additional memory allocation and often slower real-world performance than quicksort’s typical case, a genuine tradeoff, not a strictly one-sided win.
⚠️ Mistake 4: Forgetting that “sorted” has a direction
sorted([3, 1, 2], reverse=True) # [3, 2, 1] — descending, not ascendingA small, easy-to-miss detail — always confirm ascending versus descending sort direction matches what your specific task actually requires.
Quick Reference
| Algorithm | Average Case | Worst Case | Stable? | Notes |
|---|---|---|---|---|
| Bubble Sort | O(n²) | O(n²) | Yes | Educational only |
| Selection Sort | O(n²) | O(n²) | No | Educational only |
| Insertion Sort | O(n²) | O(n²) | Yes | Genuinely good for small/nearly-sorted data |
| Merge Sort | O(n log n) | O(n log n) | Yes | Guaranteed performance, extra memory |
| Quicksort | O(n log n) | O(n²) | No | Often fastest in practice, in-place |
| Timsort (Python’s built-in) | O(n log n) | O(n log n) | Yes | Hybrid, the actual production choice |
Exercises
Exercise 1 — Direct application
Implement bubble sort’s swapped early-exit optimization (already shown in this post) and confirm it correctly stops early on an already-sorted input, using a counter to verify fewer total comparisons occur compared to an already-sorted-but-unoptimized version.
Exercise 2 — Slight variation
Modify the quicksort function in this post to count and print how many total comparisons it performs, then compare that count against merge_sort’s comparison count on the same input.
Exercise 3 — Real-world combination
Write a function that sorts a list of dictionaries (representing tasks, exactly the shape used throughout this blog’s Python series) by a specified key, using Python’s built-in sorted() with the key parameter, rather than reimplementing any algorithm from this post.
Exercise 4 — Open-ended challenge
Using Python’s time module, empirically benchmark bubble_sort, merge_sort, and Python’s built-in sorted() against the same randomly generated list of 5,000 numbers, and confirm the measured timing differences roughly match this post’s Big O predictions from Post #7.
FAQ
Q: Why learn bubble sort at all if it’s never used in production? A: It is the clearest possible introduction to comparison-based sorting’s core mechanics, and understanding exactly why it’s inefficient (Post #7’s O(n²) analysis) is what makes appreciating merge sort’s and quicksort’s genuine improvements meaningful rather than abstract.
Q: Should I ever implement my own sorting algorithm in real projects? A: Almost never for general-purpose sorting — covered directly in this post’s mistakes section. Custom sorting logic is occasionally warranted for highly specialized data structures or constraints a general-purpose sort cannot accommodate, but this is a genuine exception, not the default.
Q: Is there a sorting algorithm faster than O(n log n)? A: For general comparison-based sorting, O(n log n) is a proven theoretical lower bound — no comparison-based algorithm can do better in the general case. Specialized, non-comparison-based algorithms (like counting sort, for specific, bounded-range integer data) can achieve O(n) under narrow, specific conditions, genuinely beyond this introductory post’s scope.
Q: Why does Python’s Timsort combine insertion sort and merge sort specifically? A: Real-world data is very often partially sorted already, and insertion sort is genuinely efficient on nearly-sorted data (covered above) — Timsort exploits this by detecting and directly using already-sorted “runs” within the data, falling back to merge sort’s guaranteed performance for the less-ordered portions.
Summary and Next Steps
You now understand the full spectrum of sorting algorithms — from bubble sort’s simple but O(n²) approach through merge sort’s guaranteed O(n log n) and quicksort’s typically-faster-in-practice average case — and, genuinely satisfyingly, exactly why quicksort’s real-world speed advantage over merge sort connects directly back to Post #1 and Post #3’s coverage of memory and cache locality, not just abstract algorithm design. You also know precisely what Python’s actual sort() does underneath, and why.
Your next step: Complete Exercise 4 — benchmarking bubble sort, merge sort, and Python’s built-in sort against the same data — since watching the real, measured timing gap between an O(n²) and an O(n log n) algorithm widen dramatically as you increase input size is the most concrete possible confirmation of Post #7’s growth-rate table.
Last updated: August 2026.
Share This Post

Join our newsletter!
Get the latest developer guides, tutorials, and tips delivered straight to your inbox.



